Introduction: When an AI Prediction Needs an Explanation
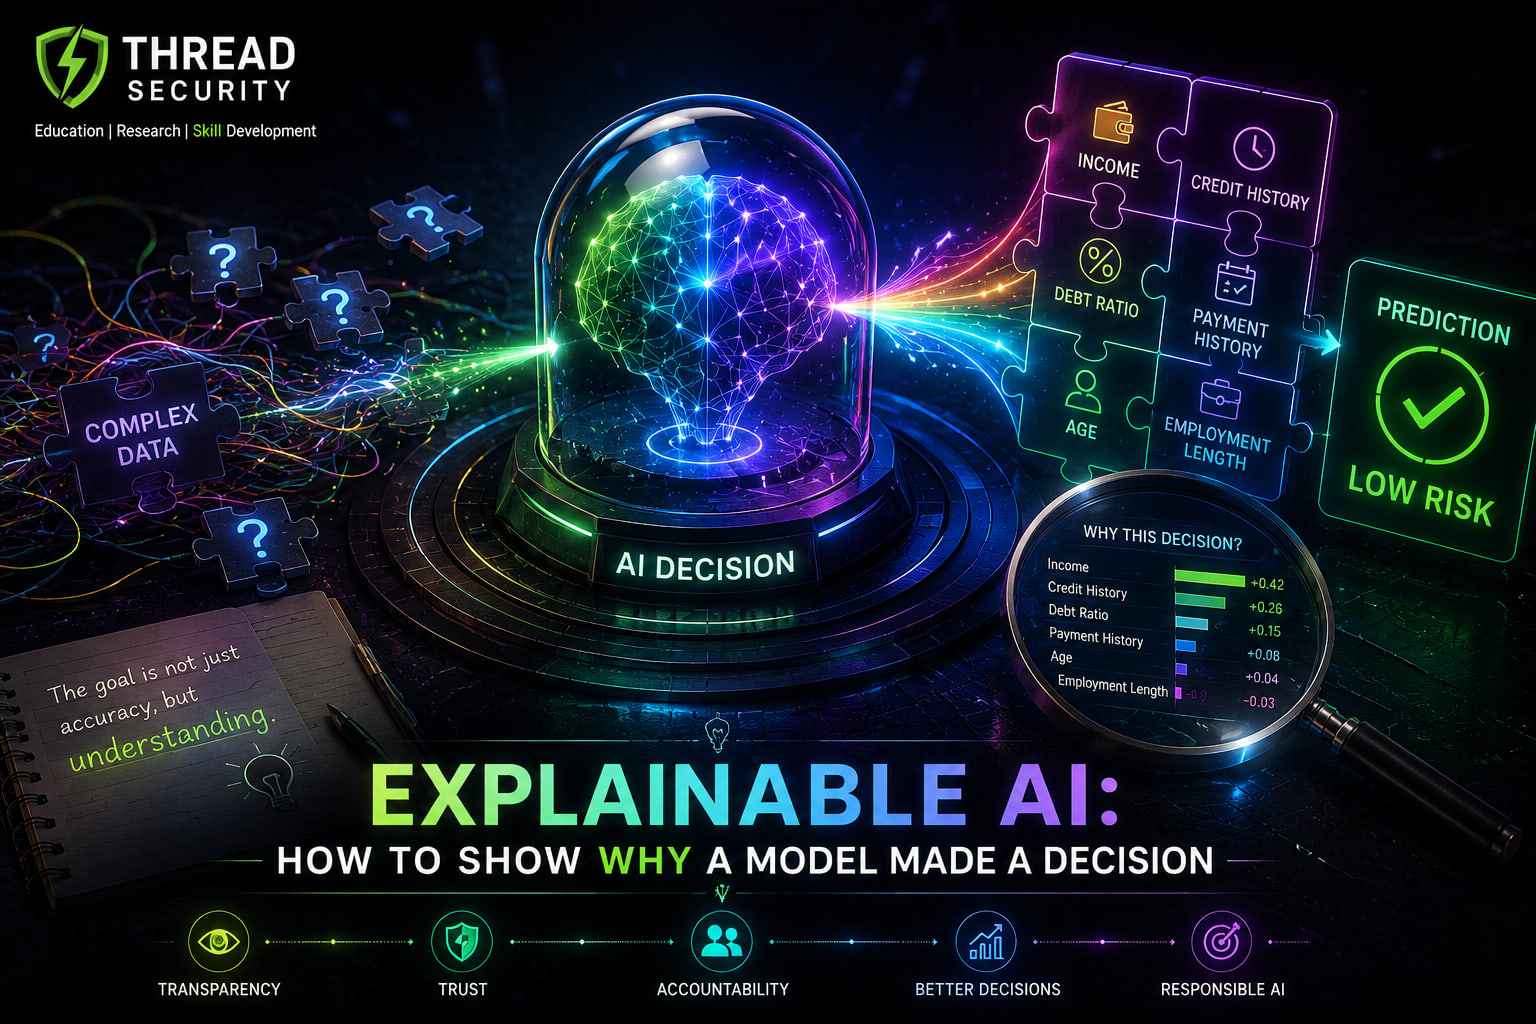
Explainable AI addresses an important question in machine learning: why did a model make a particular prediction? Imagine that a machine learning system predicts that a loan applicant has a high risk of default. The prediction may be technically correct according to the model, but the applicant, analyst, or financial institution may still need to understand which factors influenced that result.
Was the prediction influenced by income, existing debt, repayment history, or the applicant's credit utilization? Did one feature have more influence than the others? Could an unusual input have changed the result? Without an explanation, users may find it difficult to evaluate whether the model's output is reasonable.
Machine learning models can identify complex patterns, but their internal decision processes are not always easy for humans to understand. Explainability techniques help examine these decisions by estimating how different input features contribute to predictions.
In this guide, we will explore feature importance, local explanations, a small tabular example, popular tools such as SHAP and LIME, and the limitations of interpreting machine learning models.
1. What Is Explainable AI?
Explainable AI, often shortened to XAI, refers to methods and techniques that help people understand and interpret the behavior of artificial intelligence systems. It focuses on making model outputs more understandable to users, developers, analysts, and other stakeholders.
Consider two machine learning systems that predict whether a customer may cancel a subscription. Both systems produce a prediction, but their behavior may be very different.
One model might be a simple decision tree. A user can inspect its decision rules and understand how it reaches an output. Another model might be a complex ensemble or neural network that combines many learned patterns. Understanding one individual prediction may require additional interpretation techniques.
Explainability does not necessarily mean opening every internal calculation of a model. It means providing useful information about the factors and behavior associated with its predictions.
It is particularly relevant when decisions affect people, finances, access to services, safety, or other important outcomes. In these situations, simply presenting a prediction may not be sufficient.
2. Why Do Machine Learning Models Need Explanations?
A model can produce accurate predictions and still create problems if its behavior cannot be properly examined. Understanding why a model makes decisions can help teams investigate errors, communicate results, and identify unexpected patterns.
Trust and transparency: Users can better understand the reasoning associated with a prediction instead of receiving an unexplained output.
Debugging: Developers can investigate whether a model relies on irrelevant, misleading, or unexpected features.
Risk assessment: Organizations can examine whether important decisions are influenced by appropriate information.
Model improvement: Feature-level insights can help identify data problems and guide further experimentation.
Accountability: Explanations can support reviews and discussions about how an automated system is being used.
Communication: Technical teams can communicate model behavior to non-technical stakeholders more effectively.
However, an explanation is not a guarantee of correctness, fairness, or reliability. It is one source of information that should be considered alongside model evaluation, data quality, testing, and domain knowledge.
3. Understanding Feature Importance
Feature importance is one of the common ways to interpret machine learning models. A feature is an input variable used by a model to generate a prediction. In a loan-risk model, examples might include monthly income, existing debt, repayment history, and credit utilization.
Feature importance techniques estimate how influential different input variables are within a model or prediction process. They can help answer questions such as which features are most influential across a dataset or which inputs contribute most to a particular output.
For example, imagine a model trained to estimate whether a customer is likely to renew a subscription. It uses the following features:
Feature | Illustrative importance score |
|---|---|
Subscription usage | 0.40 |
Customer support history | 0.25 |
Subscription duration | 0.20 |
Plan price | 0.15 |
These hypothetical scores indicate that subscription usage has the highest estimated importance in this particular illustration. They do not mean that usage causes 40% of renewals or that changing usage will automatically change the prediction by 40%.
Different feature-importance methods calculate importance differently. Some examine how much a feature contributes to tree-based model splits, while others measure changes in model performance when feature values are disrupted.
For example, permutation importance measures how model performance changes when the values of a feature are randomly shuffled. If performance decreases substantially, the feature may contain useful predictive information for that model and evaluation dataset.
Feature importance is useful for understanding overall model behavior, but it does not necessarily explain one specific prediction.
4. Global Explanations vs Local Explanations
Two important explanation perspectives are global and local interpretability. They answer different questions and should not be treated as interchangeable.
Global explanations
A global explanation describes the overall behavior of a model across a dataset or a defined population. It helps identify which features generally influence predictions and how the model behaves across many examples.
For instance, a bank reviewing a loan-risk model may examine whether repayment history, debt levels, and income are important features across its evaluation dataset.
Global explanations are useful when developers want to understand general model patterns, investigate feature dependence, or communicate how a model behaves overall.
Local explanations
A local explanation focuses on one particular prediction. Instead of asking which features are generally important, it examines which inputs contributed to the model's output for an individual case.
For example, a subscription model may predict that a particular customer is unlikely to renew. A local explanation could indicate that declining product usage and repeated support issues contributed to that prediction.
Local explanations are useful when reviewing individual cases, investigating surprising outputs, or communicating why a particular result was generated.
A model can have different local explanations for different customers, even when the same features are used for every prediction.
5. A Small Tabular Example: Explaining a Loan-Risk Prediction
Let's understand local explanations through a simplified example. Suppose a machine learning model predicts whether a loan application belongs to a higher-risk or lower-risk category.
The model receives four input features:
Input feature | Example applicant |
|---|---|
Monthly income | ₹35,000 |
Existing monthly debt | ₹18,000 |
Repayment history | Two missed payments |
Credit utilization | 82% |
Assume the model produces a hypothetical higher-risk probability of 0.78, or 78%. This is an illustrative model output, not a real financial assessment.
A local explanation might show the following feature contributions relative to a reference prediction:
Feature | Illustrative contribution |
|---|---|
Existing monthly debt | +0.18 |
Missed payments | +0.22 |
High credit utilization | +0.15 |
Monthly income | -0.05 |
Here, positive values represent contributions towards a higher-risk prediction, while the negative value represents a contribution towards a lower-risk prediction. The values are hypothetical and are provided only to demonstrate the concept.
The explanation suggests that missed payments, existing debt, and high credit utilization contributed towards the model's higher-risk output, while income contributed in the opposite direction.
This gives an analyst more information than the probability alone. The analyst can investigate whether the input data is correct, whether the model behaves as expected, and whether the decision requires further review.
Importantly, these contribution values should be interpreted according to the specific explanation method and model output scale. They are not automatically percentages, causal effects, or proof of why an event happened.
6. Popular Tools: SHAP and LIME
Several tools can help developers generate explanations for machine learning predictions. SHAP and LIME are two widely used approaches.
SHAP: SHapley Additive exPlanations
SHAP is based on concepts from cooperative game theory. It assigns contribution values to input features to explain how they influence a model prediction relative to a reference or baseline.
For a particular prediction, SHAP values can indicate which features push the output higher and which push it lower. They can also be aggregated across multiple observations to study broader patterns.
SHAP provides different explanation visualizations, including summary plots and individual prediction plots. Its methods and computational requirements depend on the model type and selected explainer.
Official resource: SHAP Documentation.
LIME: Local Interpretable Model-agnostic Explanations
LIME explains an individual prediction by creating simplified variations of the input and observing how the original model responds to them. It then fits an interpretable model locally around the instance being explained.
For example, if a complex model predicts that a customer may cancel a subscription, LIME can help identify which input changes are associated with that prediction in the local neighborhood being examined.
LIME is model-agnostic in the sense that it can be used with different types of predictive models, provided the required prediction interface is available. Its explanations depend on the sampling strategy, neighborhood definition, and other configuration choices.
Official resource: LIME GitHub Repository.
Both tools provide useful insights, but they use different approaches. Their explanations should not be treated as interchangeable or as unquestionable descriptions of a model's internal reasoning.
7. When Is an Explanation Actually Needed?
Not every prediction requires the same level of explanation. The need depends on the application, potential consequences, users, and relevant regulatory or organizational requirements.
Financial services: Explanations can help investigate lending, credit-risk, and fraud-related model outputs.
Healthcare: Model behavior may need careful examination when AI supports clinical or operational decisions.
Recruitment: Organizations should investigate how automated screening systems use applicant information and whether inappropriate patterns influence outcomes.
Insurance: Explanations can help review predictions involving risk assessment and claims processing.
Customer applications: Explanations can help teams understand recommendations, customer segmentation, and automated support decisions.
Internal model development: Developers can use explanations to debug models and identify unexpected dependencies.
The explanation should be designed for its audience. A data scientist may need feature-level visualizations and technical metrics, while a customer or business manager may need a clear description of the important factors and relevant limitations.
8. Limitations of Explainable AI
Explainability is valuable, but it is not a perfect solution. A common mistake is assuming that once a model produces an explanation, its decisions are automatically transparent, fair, and trustworthy.
Explanations are approximations: Some techniques explain model behaviour through simplified representations rather than reproducing every internal calculation.
Different methods may disagree: Feature importance can vary depending on the selected explanation technique and its assumptions.
Correlated features create challenges: When input variables are strongly related, assigning importance to individual features may become difficult.
Explanations are not causal proof: A feature contributing to a prediction does not mean it caused the predicted outcome.
Local explanations have limited scope: An explanation for one observation does not necessarily describe how the model behaves for every other observation.
Explanations can be unstable: Small changes in inputs or method settings may sometimes produce noticeably different explanations.
Technical complexity remains: Some explanations are difficult for non-technical users to understand without suitable presentation.
There is also a risk of presenting explanations with more certainty than they deserve. A visually attractive chart does not make an underlying explanation scientifically conclusive.
For important applications, explanations should be combined with validation, fairness assessment, domain expertise, data-quality checks, and appropriate human oversight.
9. A Practical Learning Exercise
You can explore explainable AI using a small tabular dataset without building a complex deep learning system. A classification dataset with features such as age, income, spending score, or subscription activity can be used for an introductory experiment.
A simple learning workflow could involve:
Select a suitable tabular dataset and identify its input features and target variable.
Clean the data and split it into training and testing sets.
Train a basic model, such as a decision tree or random forest, using scikit-learn.
Evaluate the model using appropriate metrics for the classification task.
Use permutation importance or a suitable model-specific method to examine global feature importance.
Use SHAP or LIME to generate an explanation for an individual prediction.
Compare the explanations and document what each method reveals and what it cannot establish.
For example, you could train a model to predict whether a customer is likely to renew a subscription. After generating predictions, examine one high-risk and one low-risk example. Compare their local explanations and identify which features contributed differently.
Do not focus only on generating a chart. Ask whether the explanation is consistent with the model's behavior, whether the inputs are meaningful, and whether the result could mislead someone who does not understand the method.
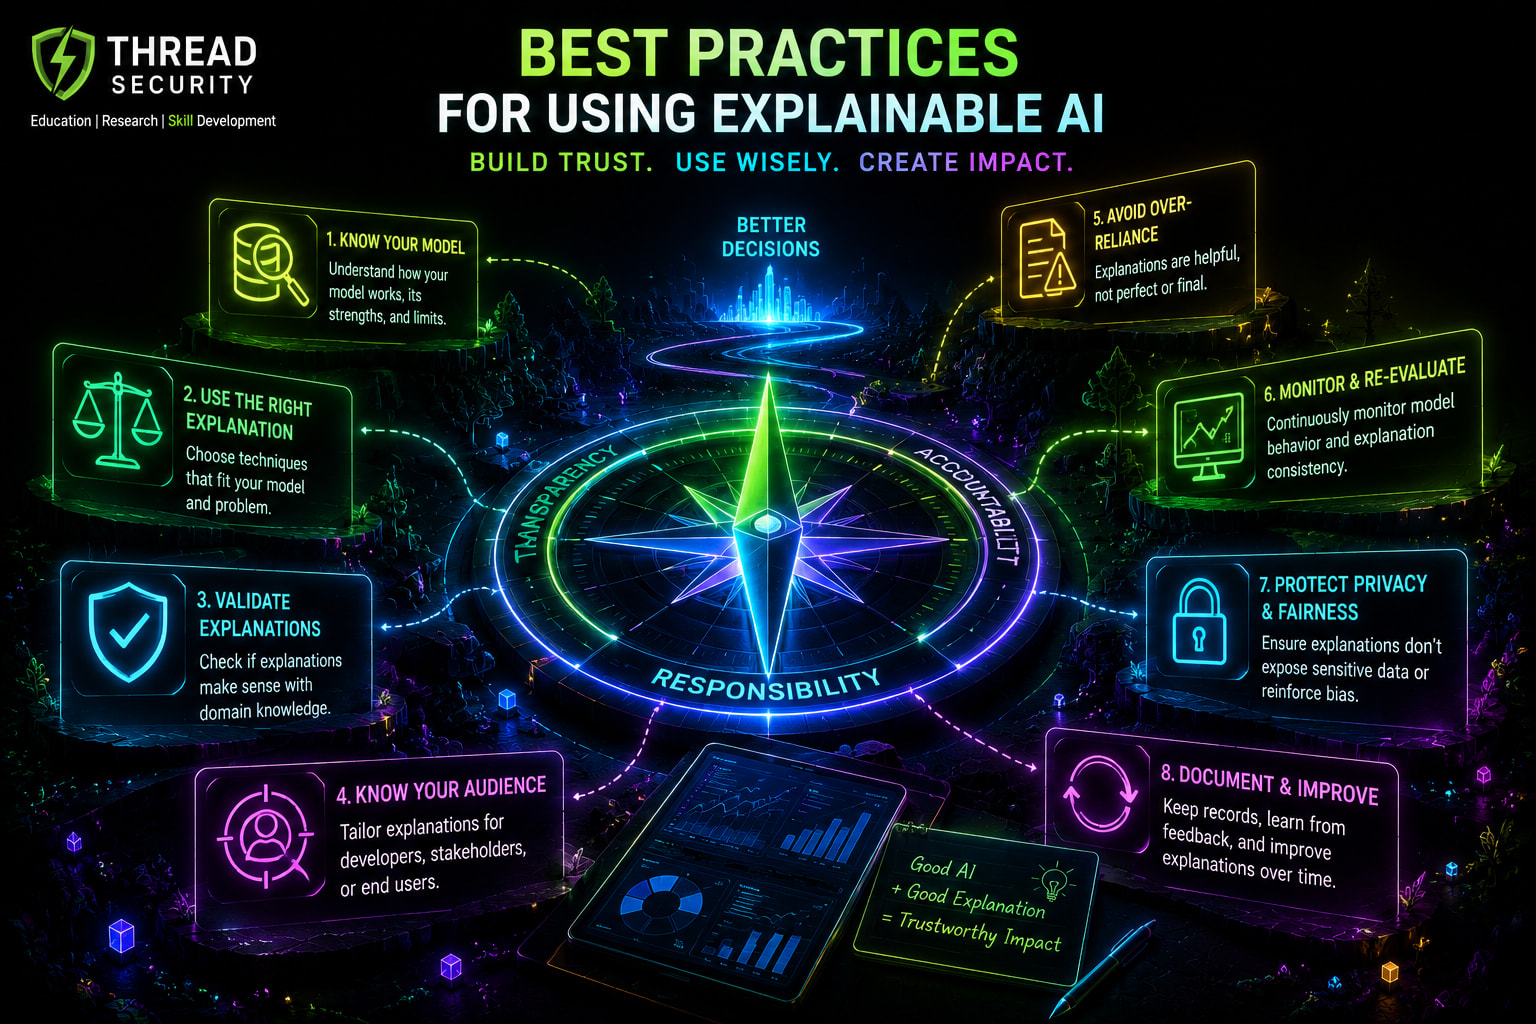
10. Best Practices for Using Explainable AI
Building explanations into an AI workflow requires more than selecting a library. Teams should decide what needs to be explained, who will use the explanation, and what decisions may follow from it.
Choose an explanation method that is appropriate for the model and intended question.
Distinguish global model behavior from individual prediction explanations.
Document the baseline, assumptions, and limitations of the selected technique.
Check for correlated inputs and possible data-quality issues.
Avoid describing feature contributions as causal relationships.
Present technical information in a format suitable for its intended audience.
Use human review where the consequences of an incorrect decision are significant.
Revisit explanations when the model, data, or application changes.
The objective is not to make every model appear simple. It is to provide useful, appropriately qualified information that helps people evaluate and question model behavior.
Frequently Asked Questions
What is explainable AI in simple terms?
Explainable AI refers to techniques that help people understand why a machine learning model produced a particular prediction and which input features influenced its output.
What is the difference between feature importance and local explanations?
Feature importance often describes the overall influence of features across a model or dataset. Local explanations focus on the factors associated with one particular prediction.
Are SHAP and LIME the same?
No. SHAP uses Shapley-value-based feature attribution, while LIME approximates a model locally using an interpretable model. Both can help explain predictions, but their methods and assumptions differ.
Does an explanation prove that an AI model is fair?
No. An explanation can reveal patterns and potential concerns, but fairness requires additional assessment using appropriate definitions, data analysis, evaluation, and human judgement.
Can explainable AI be used with complex machine learning models?
Yes. Methods such as SHAP and LIME can be applied to many complex models. However, the suitability, computational cost, and reliability of an explanation depend on the model and the method being used.
Final Thoughts: Understanding Predictions Matters
Machine learning models can generate predictions at scale, but understanding those predictions is an important part of responsible AI development. Feature importance helps examine broader patterns, while local explanations provide insights into individual model outputs.
Techniques such as SHAP and LIME give developers practical ways to investigate model behavior. However, explanations should always be interpreted carefully. They do not automatically establish causality, eliminate bias, or prove that a prediction is correct.
At Thread Security Education, we encourage learners to go beyond building machine learning models and understand how AI systems behave, how their outputs can be evaluated, and where their limitations lie. Whether you are exploring responsible AI, model interpretability, or AI courses in Jalandhar, developing these skills can help you build more informed and reliable AI applications.
Visit Thread Security to explore our learning resources and training opportunities. Learn to build AI systems, question their predictions, and explain the results with technical clarity.
Simranjit Kaur
VERIFIEDAI Trainer · Thread Security
Faculty mentor & research guide at Thread Security Education.